A petabyte archive
A petabyte archive is a digital storage system designed to retain very large collections of data for long-term access.
How big is it?
1 PB of data
Data · example
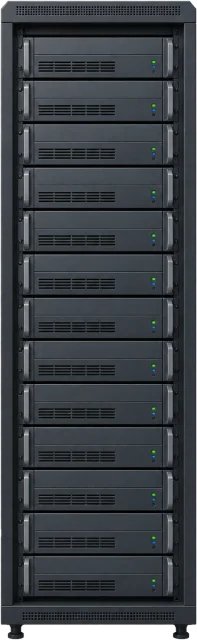
A little perspective
About 11 times the compressed warc data of Common Crawl June 2025 WARC snapshot.
Common Crawl June 2025 WARC snapshot: The Common Crawl monthly web snapshot is a large, publicly available collection of web pages and related data gathered by automated crawlers each month.
Measurements, assumptions & sources +
A petabyte archive
A defined 1 PB archive before replication or redundancy overhead.
Defined examples — our methodology
The marked data is calibrated. Unmeasured illustration details are representative.
Common Crawl June 2025 WARC snapshot
The June 2025 Common Crawl release reports 82.73 TiB of compressed WARC captures, about 91 trillion bytes. WAT, WET, indexes and uncompressed content are separate.
Common Crawl — June 2025 crawl archive
The marked compressed warc data is calibrated. Unmeasured illustration details are representative.
Change your perspective
Put it next to…
Choose a suggestion to redraw the comparison, or open its page to learn what it is.
Why this measurement?
Why we use 1 PB
For comparison, this page uses data. This is labelled example: an explicit comparison model rather than a claim that every example has the same value.
A defined 1 PB archive before replication or redundancy overhead.
The identifying illustration and the numerical comparison remain separate. How calibrated comparisons work →
Recorded properties
A petabyte archive dimensions and measurements
| Property | Selected value | Recorded range | Basis |
|---|---|---|---|
| 1 PB | Not recorded | example |
Around this scale
Go smaller. Go bigger.
These links use compatible data records, ordered around the selected value.
 Nearest lower value · DigitalCommon Crawl June 2025 WARC snapshot91 TBThe Common Crawl monthly web snapshot is a large, publicly available collection of web pages and related data gathered by automated crawlers each month.Nearest higher value · DigitalDNA storage theoretical capacity per gram215 PBDNA storage theoretical capacity per gram is the maximum amount of digital information that can be encoded in one gram of DNA under ideal conditions.
Sources and method
Want to check the number?
The source records and measurement method remain available for inspection.
More ways to see it
Curated comparisons
There’s always another scale
Follow your curiosity.
 DigitalText page3 kBA digital file containing one page of plain text characters without formatting or embedded fonts.
 DigitalCompressed photo3 MBA compressed photo is a digital image file that has been processed to reduce the amount of data needed to store or transmit it.Digital128 GB phone128 GBPhone storage is the digital memory in a mobile phone used to keep apps, photos, videos and other files.
 Digital1 TB drive1 TBA one-terabyte drive is a digital storage device capable of holding large amounts of computer data, such as documents, media and software.DigitalCommon Crawl June 2025 WARC snapshot91 TBThe Common Crawl monthly web snapshot is a large, publicly available collection of web pages and related data gathered by automated crawlers each month.DigitalAn exabyte archive1 EBAn exabyte archive is a digital storage system capable of holding extremely large datasets, often used by major organisations or data centres.DigitalDNA storage theoretical capacity per gram215 PBDNA storage theoretical capacity per gram is the maximum amount of digital information that can be encoded in one gram of DNA under ideal conditions.DigitalAutonomous vehicle sensor data per hour4 TBThe total uncompressed digital information generated by all sensors on a self-driving vehicle in one hour, including cameras, lidar and radar.